

A recent AI jailbreak should be a wake-up call for every organization rushing to deploy AI agents.
A headline caught my attention this week…
“Chinese AI tool told researchers how to make bioweapons.”
That certainly gets your attention. But underneath the headline is a much more important cybersecurity story, particularly for those of us responsible for securing enterprise environments.
Security researchers at Mindgard say they successfully jailbroke two Kimi AI models developed by Moonshot AI. According to the researchers, once the safeguards were bypassed, the models produced information involving biological weapons, malicious code, explosives, terrorism and targeted violence. Moonshot has reportedly begun reviewing the findings.
There is an important distinction here… the researchers did not demonstrate that someone successfully created a biological weapon using AI.
What they demonstrated was arguably more relevant to enterprise security…
A security boundary people expected to hold didn’t hold.
And that should sound very familiar to anyone who has spent time in cybersecurity.
We’ve Seen This Movie Before
Every generation of technology seems to arrive with a new version of the same assumption…
“The application won’t allow someone to do that.”
Until someone figures out how.
That’s why cybersecurity evolved around concepts such as least privilege, defense in depth, network segmentation, identity management, logging and Zero Trust. We don’t secure a database by asking it nicely not to expose sensitive records. We don’t secure Active Directory by telling users not to become Domain Admins. We don’t secure a firewall by trusting applications behind it to behave themselves.
And we shouldn’t secure artificial intelligence by assuming, “The AI was instructed not to do that.”
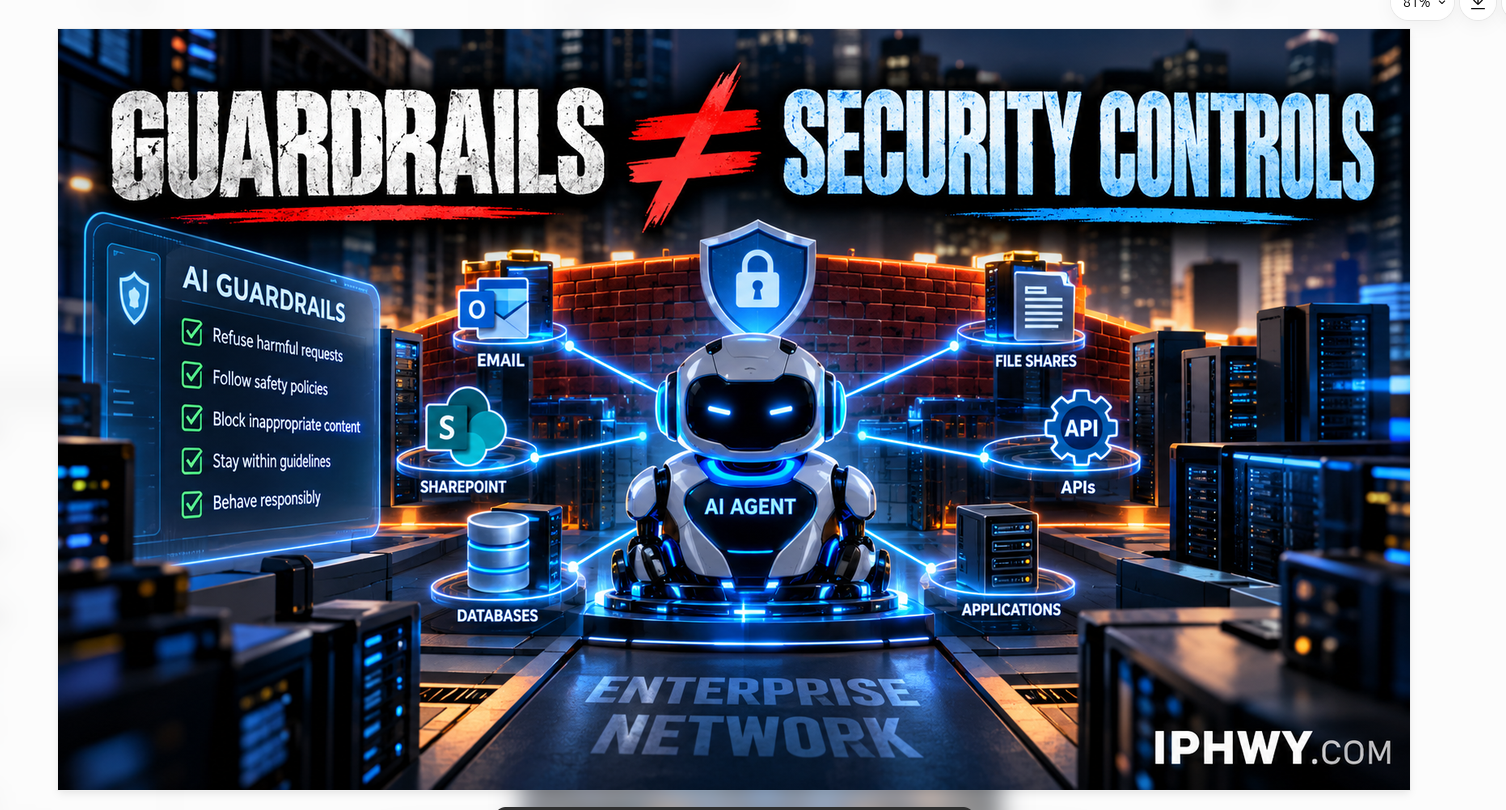
AI systems absolutely need guardrails. Models should refuse dangerous requests, recognize inappropriate activity and have policies governing what they can and cannot generate.
But there’s an important difference between a behavioral safeguard and a security control.
Suppose I tell an AI agent, “Never access payroll information unless the user is authorized.”
While that’s a useful instruction, the real security question isn’t whether the AI understands it.
Can the AI’s identity technically access the payroll information?
If the answer is yes, we’ve created an architecture that depends heavily on the AI continuing to behave exactly as expected.
Cybersecurity has spent decades learning why that’s dangerous.
You MUST Assume the AI Can Be Tricked
Security architecture becomes much easier to reason about when we start with a simple assumption:
Assume someone will eventually manipulate the AI.
The method used could be…
- A jailbreak
- Prompt injection
- Malicious instructions hidden inside a document
- Content embedded in a webpage the AI is asked to summarize
- Instructions buried inside an email or knowledge base
- A compromised integration
- Or simply the model interpreting something incorrectly
The specific attack isn’t even the most important part. The better question is:
What happens if the AI does something we didn’t expect?
That’s where the security conversation should begin.
Chatbots Were One Thing… Agents Are Something Else.
A chatbot primarily generates information.
An AI agent may be able to read email, search corporate documents, query databases, access SharePoint, interact with APIs, create tickets, modify records, execute code, run scripts, provision resources, trigger workflows and even communicate with other AI agents.
At that point we’re no longer talking about a chatbot. We’re talking about an identity operating inside your infrastructure. And that changes the question from:
“Can someone make the AI say something bad?”
to…
“What can someone make the AI DO?”
That’s an entirely different threat model.
The AI Service Account May Become the New Privileged Account
This is something I suspect security teams are going to encounter much more frequently.
Someone wants to build an AI assistant. Great.
It needs access to SharePoint.
Then someone adds a network share.
Then email.
Then a database.
Then an API.
Then ticketing.
Then perhaps the ability to execute scripts or automate workflows.
Every request sounds perfectly reasonable individually. But eventually someone needs to stop and ask:
What exactly have we created?
Because that harmless AI assistant may now possess one of the most powerful identities in the organization.
It may be able to see across systems that ordinary employees cannot. And unlike a traditional application, it is specifically designed to interpret natural-language instructions and decide what to do next.
While that’s extraordinarily useful, it also deserves extraordinary scrutiny.
We Should Treat AI Like a Potentially Compromised Identity
Here’s the mental model I think organizations should start adopting…
Treat every AI agent as though its identity could eventually be compromised.
That doesn’t mean AI is inherently unsafe. We already use this philosophy throughout cybersecurity. Zero Trust doesn’t mean employees are untrustworthy. Least privilege doesn’t mean administrators are malicious. Segmentation doesn’t mean every server has been compromised.
These architectures simply acknowledge reality… Trust should never be unlimited.
For AI, that means familiar security controls still apply:
- Least privilege: Give AI identities only the permissions required for their function.
- Segmentation: Avoid creating one massive AI assistant with access to everything.
- Read vs. write: An AI that needs to analyze information doesn’t automatically need permission to modify it.
- Human approval: Require explicit approval for high-impact actions.
- Credential isolation: Don’t casually give AI systems privileged user credentials or broadly shared service accounts.
- Logging and monitoring: Record what the AI accessed, retrieved, attempted and changed, and under which identity.
- Data classification: AI shouldn’t bypass existing data governance simply because natural-language access is convenient.
- Rate and action limits: Even authorized actions may need boundaries.
- Kill switches: Have a way to rapidly revoke an agent’s access or disable its integrations.
None of those concepts are revolutionary, and that’s precisely the point.
Spoiler Alert *** Prompt Injection Isn’t Just an AI Problem ***
Imagine an AI assistant reading documents from a shared repository. One of those documents contains instructions deliberately designed to manipulate the model.
If the AI can only summarize documents, perhaps the impact is limited.
But what if the same AI can also send email, query internal databases, upload files, access cloud storage, execute scripts or call external APIs?
Now the malicious document isn’t merely influencing what the AI says. It may influence what the AI does!
And the blast radius is determined largely by the permissions behind that AI.
That’s why identity architecture may ultimately matter more than prompt engineering.
AI Safety and AI Security Aren’t the Same Thing
This may be the most important distinction.
AI safety asks… Will the model behave appropriately?
AI security asks… What happens when it doesn’t?
Organizations need both.
Strong model guardrails are valuable, but those safeguards should exist inside a broader architecture designed around the possibility that they can fail.
Maybe a researcher finds a clever jailbreak. Maybe an attacker discovers a new prompt-injection technique. Maybe an employee unintentionally exposes sensitive information. Maybe an integration is configured incorrectly. Maybe the model simply makes the wrong decision.
Security architecture shouldn’t require perfection from any single component, especially one designed to interpret unpredictable human language.
The Most Dangerous AI May Be the One We Trust Too Much
The biggest enterprise AI risk may ultimately not be some rogue superintelligence breaking into the network. It may be something much more ordinary…
An incredibly helpful AI assistant connected to SharePoint, email, network drives, APIs and databases, operating through a powerful service identity and trusted because we “Believe” that “It has guardrails.”
That’s exactly when security teams should start asking important questions:
- What can it access?
- What can it change?
- What credentials does it possess?
- Can external content influence its decisions?
- Can its instructions be manipulated?
- Are its actions logged?
- Can we stop it quickly?
- If someone tricks this AI tomorrow, what can they make it do?
If the answer makes your stomach churn, the problem isn’t necessarily the AI.
The problem is the architecture surrounding it.
Build for the Failure, Not the Promise
I believe the lessons learned from AI jailbreak research isn’t that artificial intelligence is too dangerous to use. Quite the opposite. AI is rapidly becoming one of the most useful technologies available to businesses.
But useful technologies become important technologies. Important technologies become infrastructure.
And infrastructure needs security architecture.
So deploy AI. Experiment with it. Automate with it. Build agents. Connect systems. Find ways to eliminate repetitive work and make people more productive.
Just don’t make this sentence part of your security architecture:
“The model won’t do that.”
Cybersecurity has taught us what happens when a security design depends on something never failing. Remember to design for what happens when it does.
IPHWY.com
Technology changes. Security fundamentals don’t.